Looking for the latest information on Continuous Batching Ai S Engine? We've gathered comprehensive data, records, and insights about Continuous Batching Ai S Engine.
Important Facts
Explore the key sources for Continuous Batching Ai S Engine.
Recent Updates
Stay updated on Continuous Batching Ai S Engine's newest achievements.
Gentle Introduction to Static, Dynamic, and Continuous Batching for LLM Inference
What Is Continuous Batching Why Your GPU Sits Idle, for Your AI System Design Interview
vLLM Fully explained page attention & continuous batching in simple way
Continuous Batching: Optimize LLM Serving Throughput and Latency
Continuous Batching Explained: Iteration-Level Scheduling in vLLM (Orca Paper)
LLM Optimization Lecture 5: Continuous Batching and Piggyback Decoding
Chunked prefill, ragged batching and continuous batching
Continuous Batching Explained | vLLM vs TGI vs SGLang | LLM Inference Optimization & PagedAttention
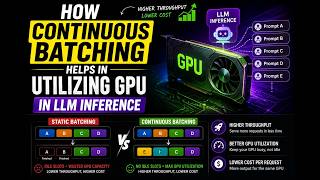
How Continuous Batching Helps In Utilizing GPU In LLM Inference | LLM | Batching
Expert Insights
Data is compiled from public records and verified media reports.
Last Updated: September 26, 2026
Final Thoughts
For 2026, Continuous Batching Ai S Engine remains one of the most talked-about information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
If you want to deploy an LLM endpoint, it is critical to think about how different requests are going to be handled. In typical ... Generating one token from a large language model means streaming every weight of the model out of memory, around 140 GB for ... Getting a model to run and getting it to handle a hundred users are different problems. Without touching the weights or changing a ... cefboud.com/posts/inside-llm-inference- A market stall stamps six name tags at once, and five of the six under the hammers are already finished. In under five minutes, one ... Want to make your Large Language Models (LLMs) run faster and more efficiently? In this video, I explain vLLM — an ... In this video, we dive deep into For the LLM inference serving techniques, We will cover Orca: A code-focused walkthrough of Chunked prefill, ragged Ever wondered how ChatGPT, DeepSeek, Claude, Gemini, and other Large Language Models (LLMs) can serve thousands of ...