Introduction on Gpu Memory Explained Model Weights Kv Cache Quantization Ep 3
Looking for the latest information on Gpu Memory Explained Model Weights Kv Cache Quantization Ep 3? We've researched comprehensive data, records, and insights about Gpu Memory Explained Model Weights Kv Cache Quantization Ep 3.
Main Features
Explore the main sources for Gpu Memory Explained Model Weights Kv Cache Quantization Ep 3.
Latest News
Stay updated on Gpu Memory Explained Model Weights Kv Cache Quantization Ep 3's latest milestones.
KV Cache Explained: Why LLMs Eat Your GPU RAM
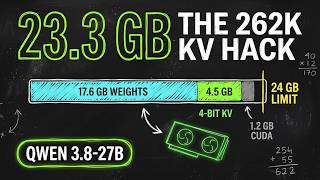
Get 262K Context on a 24GB GPU: The Qwen3.8-27B KV Cache Hack
KV Cache Explained | LLM Inference System Design and GPU Memory
Why Your GPU Runs Out of VRAM (KV Cache Explained)
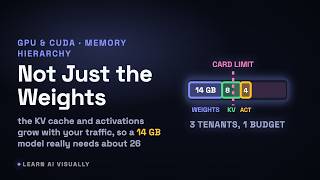
Why Smarter AI Crushes Your GPU VRAM: Weights, Activations & The KV Cache Trap
KV Cache Optimization: Speed vs Memory
Quantization Explained: Run a 70B Model on One GPU in 4 Bits, 1% Quality Cost (Inference Stack Ep 4)
The KV Cache Audit: The Real Bottleneck in LLM Scaling
Your Model Fits in VRAM. Your AI Agents Don't. (Size GPUs for KV Cache)
Why an AI Model Runs Out of GPU Memory When the Weights Fit: KV Cache and Activations
Full Guide
Data is compiled from public records and verified media reports.
Last Updated: October 2, 2026
Summary
For 2026, Gpu Memory Explained Model Weights Kv Cache Quantization Ep 3 remains one of the most talked-about information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
You downloaded a 7B parameter LLM (14GB on disk). Your Try Voice Writer - speak your thoughts and let AI handle the grammar: voicewriter.io The Twenty-four is smaller than forty-eight. So a 24 GB Why does artificial intelligence devour more
Gpu Memory Explained Model Weights Kv Cache Quantization Ep 3.pdf
What is the most accurate information about Gpu Memory Explained Model Weights Kv Cache Quantization Ep 3?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Gpu Memory Explained Model Weights Kv Cache Quantization Ep 3.
Why is Gpu Memory Explained Model Weights Kv Cache Quantization Ep 3 trending right now?
Interest in Gpu Memory Explained Model Weights Kv Cache Quantization Ep 3 has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Gpu Memory Explained Model Weights Kv Cache Quantization Ep 3?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Gpu Memory Explained Model Weights Kv Cache Quantization Ep 3 updated?
We regularly update our database with the latest information, media, and analysis related to Gpu Memory Explained Model Weights Kv Cache Quantization Ep 3.