Background to Iterative Length Regularization For Dpo Python Implementation
Looking for the latest information on Iterative Length Regularization For Dpo Python Implementation? We've researched comprehensive data, records, and insights about Iterative Length Regularization For Dpo Python Implementation.
Main Features
Explore the primary sources for Iterative Length Regularization For Dpo Python Implementation.
Latest News
Stay updated on Iterative Length Regularization For Dpo Python Implementation's latest milestones.
DPO Coding | Direct Preference Optimization (DPO) Code implementation | DPO in LLM Alignment
Chap 6: Iterative regularization methods - 1
Direct Preference Optimization (DPO)
Direct Preference Optimization (DPO) - Learn how to fine-tune LLMs directly without RL.
Direct Preference Optimization or DPO is out and TR-DPO is in | New LLM Paper
Direct Preference Optimization (DPO) explained + OpenAI Fine-tuning example
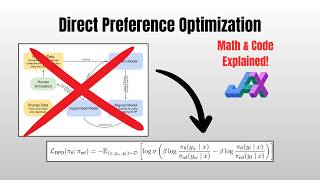
Direct Preference Optimization: DPO Math & JAX Implementation [Road to Reasoning #8]
Direct Preference Optimization: Your Language Model is Secretly a Reward Model | DPO paper explained
Direct Preference Optimization (DPO): Teach an LLM to Answer Better
Direct Preference Optimization Beats RLHF (Explained Visually), how DPO works
DPO | Direct Preference Optimization (DPO) architecture | LLM Alignment
Detailed Analysis
Data is compiled from public records and verified media reports.
Last Updated: September 29, 2026
Summary
For 2026, Iterative Length Regularization For Dpo Python Implementation remains one of the most talked-about information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Iterative Length Regularization for DPO Direct Preference Optimization ( The standard Reinforcement Learning from Human Feedback (RLHF) pipeline—involving reward model training and complex ... Produces solutions that actually tend to to look Get the Dataset: huggingface.co/datasets/Trelis/hh-rlhf- Paper : huggingface.co/papers/2404.09656 TWITTER: twitter.com/rohanpaul_ai Checkout the MASSIVELY ... In this guide, I will explore Direct Preference Optimization ( We saw how complex RLHF was, both conceptually and in practice. Not only was it hard to Supervised fine-tuning teaches a model the right facts. But "correct" isn't the same as "good" — a support answer can have every ...
Iterative Length Regularization For Dpo Python Implementation.pdf
What is the most accurate information about Iterative Length Regularization For Dpo Python Implementation?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Iterative Length Regularization For Dpo Python Implementation.
Why is Iterative Length Regularization For Dpo Python Implementation trending right now?
Interest in Iterative Length Regularization For Dpo Python Implementation has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Iterative Length Regularization For Dpo Python Implementation?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Iterative Length Regularization For Dpo Python Implementation updated?
We regularly update our database with the latest information, media, and analysis related to Iterative Length Regularization For Dpo Python Implementation.