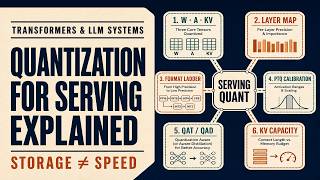
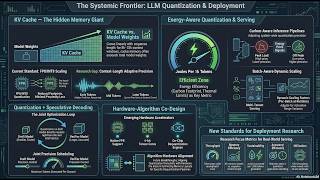
Overview on Llm Quantization For Serving Weights Activations And Kv Cache Quantization Explained
Looking for the latest information on Llm Quantization For Serving Weights Activations And Kv Cache Quantization Explained? We've researched comprehensive data, records, and insights about Llm Quantization For Serving Weights Activations And Kv Cache Quantization Explained.
Core Information
Explore the main sources for Llm Quantization For Serving Weights Activations And Kv Cache Quantization Explained.
History
Stay updated on Llm Quantization For Serving Weights Activations And Kv Cache Quantization Explained's latest milestones.
Optimize Your AI - Quantization Explained
KV Cache: The Trick That Makes LLMs Faster
How Do We Get MASSIVE Model To Run On Device Quantization Explained.
LLM Quantization Explained: GPTQ, AWQ, QLoRA, GGUF and More
How LLM Inference Actually Works (Prefill, Decode, KV Cache, Quantization)
LLM Inference and KV Cache Explained: Memory, Context, Routing and Quantization
Quantization & KV cache
Quantization Explained: How to make AI models smaller and faster
Deep Dive
Data is compiled from public records and verified media reports.
Last Updated: September 28, 2026
Final Thoughts
For 2026, Llm Quantization For Serving Weights Activations And Kv Cache Quantization Explained remains one of the most searched-for information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Free newsletter: multiagentacademy.substack.com/ Try Voice Writer - speak your thoughts and let AI handle the grammar: voicewriter.io The In this video, we discuss the fundamentals of model Run massive AI models on your laptop! Learn the secrets of In this deep dive, we'll explain how every modern Large Language Model, from LLaMA to GPT-4, uses the Every time I do a video about a model I get a saying "Well you never said what it takes to run it!" Well since I am not ... To produce one word, a language model has to look back at every word that came before it and run the entire stack of attention ... Inference is now where the money goes — in 2026, companies spend more running AI models than training them. In this video I ... Slides: docs.google.com/presentation/d/1bNzOJNoF8SjHoijJky1AN5TxqdQd84yIfeSVhqXEv48/edit?usp=sharing.
Llm Quantization For Serving Weights Activations And Kv Cache Quantization Explained.pdf
What is the most accurate information about Llm Quantization For Serving Weights Activations And Kv Cache Quantization Explained?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Llm Quantization For Serving Weights Activations And Kv Cache Quantization Explained.
Why is Llm Quantization For Serving Weights Activations And Kv Cache Quantization Explained trending right now?
Interest in Llm Quantization For Serving Weights Activations And Kv Cache Quantization Explained has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Llm Quantization For Serving Weights Activations And Kv Cache Quantization Explained?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Llm Quantization For Serving Weights Activations And Kv Cache Quantization Explained updated?
We regularly update our database with the latest information, media, and analysis related to Llm Quantization For Serving Weights Activations And Kv Cache Quantization Explained.