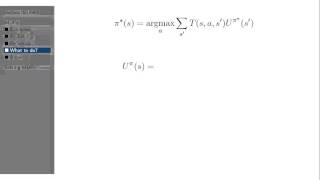Looking for the latest information on Mdps The Value Function? We've researched comprehensive data, records, and insights about Mdps The Value Function.
Main Features
Explore the main sources for Mdps The Value Function.
Developments
Stay updated on Mdps The Value Function's latest milestones.
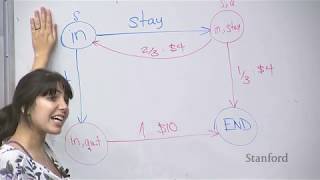
Markov Decision Processes 1 - Value Iteration | Stanford CS221: AI (Autumn 2019)
RL Course by David Silver - Lecture 2: Markov Decision Process
Value Functions - Fundamentals of Reinforcement Learning
Lecture 17 - MDPs & Value/Policy Iteration | Stanford CS229: Machine Learning Andrew Ng (Autumn2018)
Policy and Value Iteration
Markov Decision Process (MDP) - 5 Minutes with Cyrill
Connection to MDPs
MDP & RL: Value Function and Bellman Equation - Reinforcement Learning in Finance
Model Based Reinforcement Learning: Policy Iteration, Value Iteration, and Dynamic Programming
Mastering MDPs: Understanding Optimal Values V* and Q* Values
Detailed Analysis
Data is compiled from public records and verified media reports.
Last Updated: September 26, 2026
Future Outlook
For 2026, Mdps The Value Function remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
How does reinforcement learning find the best decision for every possible state? In this video, we explore Dive into the core concepts of Reinforcement Learning! This video breaks down Markov Decision Processes ( For more information about Stanford's Artificial Intelligence professional and graduate programs, visit: stanford.io/3pUNqG7 ... Once the problem is formulated as an MDP, finding the optimal policy is more efficient when using 0.1 is the probability of transitioning to that state and then the reward again is going to be zero and the This video is part of the Udacity course "Reinforcement Learning". Watch the full course at udacity.com/course/ud600. Here we introduce dynamic programming, which is a cornerstone of model-based reinforcement learning. We demonstrate ... n this video, we dive deep into Markov Decision Processes (