Overview to Model Optimizer Fast Tensorrt Inference With Quantization Pruning
Looking for the latest information on Model Optimizer Fast Tensorrt Inference With Quantization Pruning? We've compiled comprehensive data, records, and insights about Model Optimizer Fast Tensorrt Inference With Quantization Pruning.
Main Features
Explore the primary sources for Model Optimizer Fast Tensorrt Inference With Quantization Pruning.
Latest News
Stay updated on Model Optimizer Fast Tensorrt Inference With Quantization Pruning's newest achievements.
Model Quantization: Unlock ⚡Faster⚡ Inference Speeds
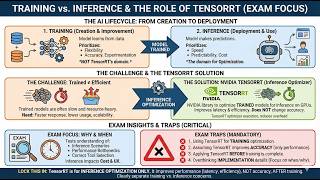
Introduction to NVIDIA TensorRT for High Performance Deep Learning Inference
Making Computer Vision Models Faster: An Introduction to TensorRT Optimization
NVIDIA AI Revolutionizes Inference: TensorRT Model Optimizer for GPU Efficiency
ML Model Optimization: Quantization & Pruning Explained
FP32 vs FP16 vs INT8 — What Actually Changes (TensorRT)
Episode 17: TensorRT & Inference Optimization
TensorRT & TensorRT-LLM Explained — The Complete Guide | From Model to Production in 12 Minutes
NVidia TensorRT: high-performance deep learning inference accelerator (TensorFlow Meets)
INT8 Inference of Quantization-Aware trained models using ONNX-TensorRT
Boost Deep Learning Inference Performance with TensorRT | Step-by-Step
Full Guide
Data is compiled from public records and verified media reports.
Last Updated: September 30, 2026
Future Outlook
For 2026, Model Optimizer Fast Tensorrt Inference With Quantization Pruning remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
In many applications of deep learning Try Voice Writer - speak your thoughts and let AI handle the grammar: voicewriter.io Four techniques to Hi everyone! In the last video we've seen how to accelerate the speed of our programs with Pytorch and CUDA - today we will ... With IntegraPose, user can train powerful, custom, Modern computer vision applications demand real-time performance, yet many deep learning NVIDIA AI is pushing the boundaries of What actually happens when you take an AI By the end of this lecture, you will be able to: • Understand what In this episode of TensorFlow Meets, we are joined by Chris Gottbrath from NVidia and X.Q. from the Google Brain team to talk ... Accelerating Deep Neural Networks (DNN)
Model Optimizer Fast Tensorrt Inference With Quantization Pruning.pdf
What is the most accurate information about Model Optimizer Fast Tensorrt Inference With Quantization Pruning?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Model Optimizer Fast Tensorrt Inference With Quantization Pruning.
Why is Model Optimizer Fast Tensorrt Inference With Quantization Pruning trending right now?
Interest in Model Optimizer Fast Tensorrt Inference With Quantization Pruning has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Model Optimizer Fast Tensorrt Inference With Quantization Pruning?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Model Optimizer Fast Tensorrt Inference With Quantization Pruning updated?
We regularly update our database with the latest information, media, and analysis related to Model Optimizer Fast Tensorrt Inference With Quantization Pruning.