Looking for the latest information on Pacman Mdp Solver Value Iteration? We've gathered comprehensive data, records, and insights about Pacman Mdp Solver Value Iteration.
Important Facts
Explore the primary sources for Pacman Mdp Solver Value Iteration.
Developments
Stay updated on Pacman Mdp Solver Value Iteration's newest achievements.
Model Based Reinforcement Learning: Policy Iteration, Value Iteration, and Dynamic Programming
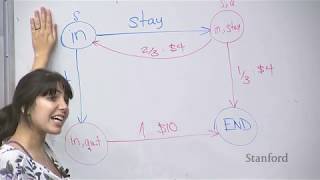
Markov Decision Processes 1 - Value Iteration | Stanford CS221: AI (Autumn 2019)
Introduction to MDPs and value iteration
Lecture 17 - MDPs & Value/Policy Iteration | Stanford CS229: Machine Learning Andrew Ng (Autumn2018)
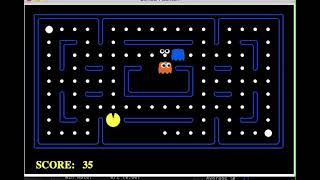
Pacman Reinforcement CS188
Markov Decision Process (MDP) - 5 Minutes with Cyrill
Value Iteration Algorithm - Dynamic Programming Algorithms in Python (Part 9)
Markovian PacMan
PacMan - MDP Agent AI - mediumClassic Map Run
RL Course by David Silver - Lecture 2: Markov Decision Process
Section 3 Worksheet Solutions: MDPs
Full Guide
Data is compiled from public records and verified media reports.
Last Updated: September 30, 2026
Conclusion
For 2026, Pacman Mdp Solver Value Iteration remains one of the most talked-about information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
For more information about Stanford's Artificial Intelligence professional and graduate programs, visit: stanford.io/3pUNqG7 ... Mastering Reinforcement Learning In this video, we show how to code This is a single run using Berkley ... the value of a state is the optimal expected sum of discounted Rewards acting in the