Overview of Paper Presentation 4 Transformers Without Normalization
Looking for the latest information on Paper Presentation 4 Transformers Without Normalization? We've gathered comprehensive data, records, and insights about Paper Presentation 4 Transformers Without Normalization.
Key Details
Explore the primary sources for Paper Presentation 4 Transformers Without Normalization.
Recent Updates
Stay updated on Paper Presentation 4 Transformers Without Normalization's latest milestones.
Visualizing transformers and attention | Talk for TNG Big Tech Day '24
Transformers are RNNs: Fast Autoregressive Transformers with Linear Attention (Paper Explained)
Attention in transformers, step-by-step | Deep Learning Chapter 6
Linear Transformers Are Secretly Fast Weight Memory Systems (Machine Learning Paper Explained)
Transformers, the tech behind LLMs | Deep Learning Chapter 5
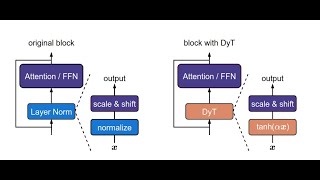
Transformers without Normalization
Attention is all you need (Transformer) - Model explanation (including math), Inference and Training
Transformer Neural Networks Derived from Scratch
Let's build GPT: from scratch, in code, spelled out.
How might LLMs store facts | Deep Learning Chapter 7
Illustrated Guide to Transformers Neural Network: A step by step explanation
Deep Dive
Data is compiled from public records and verified media reports.
Last Updated: September 30, 2026
Conclusion
For 2026, Paper Presentation 4 Transformers Without Normalization remains one of the most talked-about information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Chapters 00:00 - 03:45 Introduction 03:45 - 16:06 Methodology 16:06 - 21:25 Results 21:25 - 39:46 Analysis 39:46 - 43:56 ... This video presents a summary of the CVPR 2025 An overview of transforms, as used in LLMs, and the attention mechanism within them. Based on the 3blue1brown deep learning ... Demystifying attention, the key mechanism inside Breaking down how Large Language Models work, visualizing how data flows through. Instead of sponsored ad reads, these ... arxiv.org/abs//2503.10622 YouTube: youtube.com/ TikTok: tiktok.com/ A complete explanation of all the layers of a We build a Generatively Pretrained Unpacking the multilayer perceptrons in a
Paper Presentation 4 Transformers Without Normalization.pdf
What is the most accurate information about Paper Presentation 4 Transformers Without Normalization?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Paper Presentation 4 Transformers Without Normalization.
Why is Paper Presentation 4 Transformers Without Normalization trending right now?
Interest in Paper Presentation 4 Transformers Without Normalization has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Paper Presentation 4 Transformers Without Normalization?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Paper Presentation 4 Transformers Without Normalization updated?
We regularly update our database with the latest information, media, and analysis related to Paper Presentation 4 Transformers Without Normalization.