Overview on Part 4 Attention Approximates Sparse Distributed Memory
Looking for the latest information on Part 4 Attention Approximates Sparse Distributed Memory? We've researched comprehensive data, records, and insights about Part 4 Attention Approximates Sparse Distributed Memory.
Main Features
Explore the key sources for Part 4 Attention Approximates Sparse Distributed Memory.
History
Stay updated on Part 4 Attention Approximates Sparse Distributed Memory's newest achievements.
AI / Neuroscience Chat Episode 2: Basics of sparse distributed representations
Distributed-Memory Sparse Kernels for Machine Learning
Modeling Data Streams Using Sparse Distributed Representations
F18 Recitation 9 - Attention Networks HW4 Primer
Pentti Kanerva - Computing in Superposition in the Classical Domain
Processor's View of Memory - Georgia Tech - HPCA: Part 4
EfficientML.ai Lecture 4 - Pruning and Sparsity (Part II) (MIT 6.5940 Fall 2026)
What is Sparse Attention
NSA How Native Sparse Attention Makes Ultra-Long Contexts Fast
Unstructured Sparsity Meets Tensor Cores: Lessons from Sparse Attention and MoE
Sparse Distributed Representation - COT4401
Detailed Analysis
Data is compiled from public records and verified media reports.
Last Updated: October 1, 2026
Future Outlook
For 2026, Part 4 Attention Approximates Sparse Distributed Memory remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
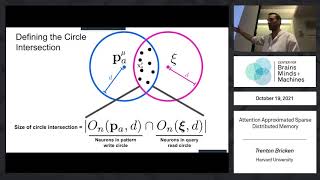
Now I want to explain this amazing article Trenton Bricken, Harvard University Abstract: While Our research intern Alex Cuozzo discusses the book Presentation by Vivek Bharadwaj (UC Berkeley) for the IPDPS'22 paper Vivek Bharadwaj, Aydın Buluç, James Demmel. In this screencast, Jeff Hawkins narrates the presentation he gave at a workshop called "From Data to Knowledge: ... Talk by Pentti Kanerva given at a meeting of The Redwood Center for Theoretical Neuroscience at UC Berkeley. Abstract: The ... Watch on Udacity: udacity.com/course/viewer the full High ... Aparna Chandramowlishwaran (UC Irvine) simons.berkeley.edu/talks/aparna-chandramowlishwaran-uc-irvine-2025-10-21 ... This is the presentation to accompany the research paper of the same title.
Part 4 Attention Approximates Sparse Distributed Memory.pdf
What is the most accurate information about Part 4 Attention Approximates Sparse Distributed Memory?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Part 4 Attention Approximates Sparse Distributed Memory.
Why is Part 4 Attention Approximates Sparse Distributed Memory trending right now?
Interest in Part 4 Attention Approximates Sparse Distributed Memory has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Part 4 Attention Approximates Sparse Distributed Memory?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Part 4 Attention Approximates Sparse Distributed Memory updated?
We regularly update our database with the latest information, media, and analysis related to Part 4 Attention Approximates Sparse Distributed Memory.