Positional Encoding in Transformers | Deep Learning | CampusX
Positional Encoding | How LLMs understand structure
How Rotary Position Embedding Supercharges Modern LLMs [RoPE]
Rotary Positional Encodings | Explained Visually
Positional Encoding in Transformers Simplified
Detailed Analysis
Data is compiled from public records and verified media reports.
Last Updated: September 30, 2026
Future Outlook
For 2026, Postitional Encoding remains one of the most talked-about information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
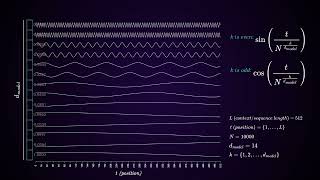
What are positional embeddings and why do transformers need Grant Sanderson of 3Blue1Brown and Alok Puranik, a researcher at Jane Street, work through Alok's latest blog post on Transformers process tokens in parallel — so how do they understand word order? In this video, we explore For more information about Stanford's Artificial Intelligence programs visit: stanford.io/ai This lecture is from the Stanford ... Timestamps: 0:00 Intro 0:42 Problem with Self-attention 2:30 Transformer models can generate language really well, but how do they do it? A very important step of the pipeline is the ... Why can't a Transformer tell "Dog bites Man" from "Man bites Dog"? Because without In this video, I have tried to have a comprehensive look at In this lecture, we learn about Rotary In this tutorial, you will learn about the concept of