Background on Python Llm Api Cache Rate Limit To Slash Cost Latency
Looking for the latest information on Python Llm Api Cache Rate Limit To Slash Cost Latency? We've researched comprehensive data, records, and insights about Python Llm Api Cache Rate Limit To Slash Cost Latency.
Key Details
Explore the primary sources for Python Llm Api Cache Rate Limit To Slash Cost Latency.
Developments
Stay updated on Python Llm Api Cache Rate Limit To Slash Cost Latency's latest milestones.
How Prompt Caching Cuts LLM Latency | Code For Data
Semantic Caching Explained for LLMs in 4 Minutes | Trick to Save Token Cost
Prompt Caching: Cut Your LLM Cost and Latency
Prompt Caching Reduced My Agent Costs by 90%
Caching Strategies to Slash Your LLM Bill | Prompt & Semantic Caching Explained with Demo
Prompt vs. Semantic Caching: The Secret to 15x Faster & 90% Cheaper AI Agents
LLM Caching with Redis + Qdrant | Cut API Cost & Latency Fast
Prompt caching: cut LLM costs up to 90% | Built With AI
Deep Dive
Data is compiled from public records and verified media reports.
Last Updated: September 29, 2026
Conclusion
For 2026, Python Llm Api Cache Rate Limit To Slash Cost Latency remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
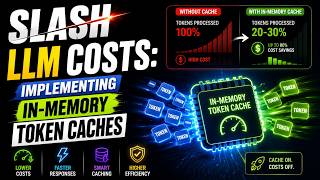
Ready to become a certified watsonx Generative AI Engineer? Register now and use code IBMTechYT20 for 20% off of your exam ... In this video I will show you how to use Send the same request twice. The second time can Stop paying for the same context twice! Learn how to implement in-memory token Because of the global GPU shortage, all Large Language Model ( Learn how to cut your Mastra agent's input token Are your AI agents slow, expensive, or repetitive? Large Language Models (LLMs) often waste significant time and money ... If you resend the same big context every call, you're overpaying. Prompt
Python Llm Api Cache Rate Limit To Slash Cost Latency.pdf
What is the most accurate information about Python Llm Api Cache Rate Limit To Slash Cost Latency?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Python Llm Api Cache Rate Limit To Slash Cost Latency.
Why is Python Llm Api Cache Rate Limit To Slash Cost Latency trending right now?
Interest in Python Llm Api Cache Rate Limit To Slash Cost Latency has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Python Llm Api Cache Rate Limit To Slash Cost Latency?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Python Llm Api Cache Rate Limit To Slash Cost Latency updated?
We regularly update our database with the latest information, media, and analysis related to Python Llm Api Cache Rate Limit To Slash Cost Latency.