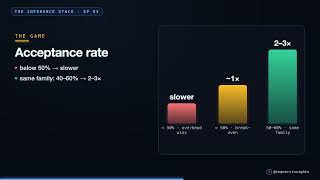
Introduction of Speculative Decoding Explained The Small Model That Makes Llms 3x Faster Inference Stack Ep 3
Looking for the latest information on Speculative Decoding Explained The Small Model That Makes Llms 3x Faster Inference Stack Ep 3? We've gathered comprehensive data, records, and insights about Speculative Decoding Explained The Small Model That Makes Llms 3x Faster Inference Stack Ep 3.
Important Facts
Explore the main sources for Speculative Decoding Explained The Small Model That Makes Llms 3x Faster Inference Stack Ep 3.
Latest News
Stay updated on Speculative Decoding Explained The Small Model That Makes Llms 3x Faster Inference Stack Ep 3's latest milestones.
Speculative Decoding: Make Your LLM Inference 2x-3x Faster
Speculative Decoding: How LLMs Go 2-3x Faster
Speculative Decoding: EAGLE-3 Makes LLMs 3–6.5× Faster | 5-Min Bite
Speculative Decoding: How Draft Models 3X Local LLM Inference
What is Speculative Decoding making LLMs faster
Speculative Decoding: How to Make Any LLM 3x Faster (For Free)
Speculative Decoding & Inference Speed — 2-3x Faster LLMs With Zero Quality Loss
MTP Speculative Decoding Explained: How AI Models Generate Faster
Speculative Decoding: 3× Faster LLM Inference with Zero Quality Loss
Speculative Decoding: Faster LLMs, Same Output
Deep Dive
Data is compiled from public records and verified media reports.
Last Updated: September 25, 2026
Summary
For 2026, Speculative Decoding Explained The Small Model That Makes Llms 3x Faster Inference Stack Ep 3 remains one of the most talked-about information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Your GPU writes one word at a time. Ready to become a certified watsonx AI Assistant Engineer? Register now and use code IBMTechYT20 for 20% off of your exam ... Your GPU can do trillions of operations a second, so why does a chatbot type one word at a time? It is barely computing at all. Try Voice Writer - speak your thoughts and let AI handle the grammar: voicewriter.io
Speculative Decoding Explained The Small Model That Makes Llms 3x Faster Inference Stack Ep 3.pdf
What is the most accurate information about Speculative Decoding Explained The Small Model That Makes Llms 3x Faster Inference Stack Ep 3?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Speculative Decoding Explained The Small Model That Makes Llms 3x Faster Inference Stack Ep 3.
Why is Speculative Decoding Explained The Small Model That Makes Llms 3x Faster Inference Stack Ep 3 trending right now?
Interest in Speculative Decoding Explained The Small Model That Makes Llms 3x Faster Inference Stack Ep 3 has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Speculative Decoding Explained The Small Model That Makes Llms 3x Faster Inference Stack Ep 3?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Speculative Decoding Explained The Small Model That Makes Llms 3x Faster Inference Stack Ep 3 updated?
We regularly update our database with the latest information, media, and analysis related to Speculative Decoding Explained The Small Model That Makes Llms 3x Faster Inference Stack Ep 3.