Looking for the latest information on Uoft Rl Course Lecture 26 Td Lambda? We've researched comprehensive data, records, and insights about Uoft Rl Course Lecture 26 Td Lambda.
Important Facts
Explore the primary sources for Uoft Rl Course Lecture 26 Td Lambda.
Data is compiled from public records and verified media reports.
Last Updated: September 29, 2026
Final Thoughts
For 2026, Uoft Rl Course Lecture 26 Td Lambda remains one of the most talked-about information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
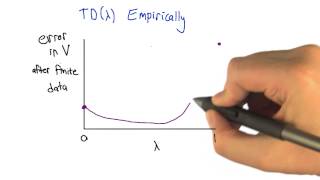
We can improve sample efficiency by averaging This video is part of the Udacity In this ECE 8851: Reinforcement Learning We introduce the notion of reinforcement learning and understand how it differs to classic learning tasks in its nature. We start with the multi-armed bandit problem, and see how optimally or randomly playing could change the collected reward. We learn policy networks and their learning objectives. We see how er can formulate their objective to train a computational policy ... We extend the idea of bootstrapping to estimate values from deeper temporal differences. This is called We go over a quick history of Deep The value function enables us to define the notion of Optimal Policy. This formulates concretely the main objective in We see that the best way to present the environment mathematically is to look at it as a state-dependent system. This provides us ... Free PDF: incompleteideas.net/book/RLbook2018.pdf Print Version: ...