Introduction of Writing Llm Server Part 8 Implementing Dynamic Batching
Looking for the latest information on Writing Llm Server Part 8 Implementing Dynamic Batching? We've compiled comprehensive data, records, and insights about Writing Llm Server Part 8 Implementing Dynamic Batching.
Core Information
Explore the key sources for Writing Llm Server Part 8 Implementing Dynamic Batching.
Developments
Stay updated on Writing Llm Server Part 8 Implementing Dynamic Batching's newest achievements.
I Built a Production Model-Serving Engine from Scratch — Live Inference, Batching & Real Benchmarks
How LLM Inference Actually Scales: KV Cache, Batching & vLLM
L-52: Continuous batching – vs Static Batching for LLM Inference #llm #inference
How to Scale LLM Applications With Continuous Batching!
Project Lightning Talk: From Static Slices To Elastic GPUs: Dynamic MIG With HAMI - 纪飞 王, Dynamia
Self Hosted LLMs: Running Your Own Inference Infrastructure
[vLLM Office Hours #39] Intro to batch invariant in vLLM - January 8, 2026
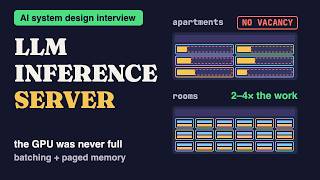
Design an LLM Inference Server for Your AI System Design Interview
Most devs don't understand how LLM tokens work
Batch 08 Output with Echo
Detailed Analysis
Data is compiled from public records and verified media reports.
Last Updated: September 29, 2026
Final Thoughts
For 2026, Writing Llm Server Part 8 Implementing Dynamic Batching remains one of the most searched-for information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
In this episode, we fix the elephant in the room from earlier Generating one token from a large language model means streaming every weight of the model out of memory, around 140 GB for ... Nexus Serve — a high-performance model serving & inference engine, demonstrated entirely with live, measured data. No mock ... Getting a model to run and getting it to handle a hundred users are different problems. Without touching the weights or changing a ... Project Lightning Talk: From Static Slices To Elastic GPUs: A talk by Daniel Burkhardt Cerigo from datavaluepeople When does it make sense to run your own In this vLLM Office Hours recording, we dive into At nine at night a GPU serving a chatbot "runs out of memory" — and most of that memory is empty. This is how an If you would to support me, please , & , and check me out on Patreon: ...
Writing Llm Server Part 8 Implementing Dynamic Batching.pdf
What is the most accurate information about Writing Llm Server Part 8 Implementing Dynamic Batching?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Writing Llm Server Part 8 Implementing Dynamic Batching.
Why is Writing Llm Server Part 8 Implementing Dynamic Batching trending right now?
Interest in Writing Llm Server Part 8 Implementing Dynamic Batching has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Writing Llm Server Part 8 Implementing Dynamic Batching?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Writing Llm Server Part 8 Implementing Dynamic Batching updated?
We regularly update our database with the latest information, media, and analysis related to Writing Llm Server Part 8 Implementing Dynamic Batching.