Expectation Maximization Algorithm | Intuition & General Derivation
Expectation Maximization for the Gaussian Mixture Model | Full Derivation
Deriving the EM Algorithm for the Multivariate Gaussian Mixture Model
(ML 16.3) Expectation-Maximization (EM) algorithm
Bayesian Networks 9 - EM Algorithm | Stanford CS221: AI (Autumn 2021)
EM Algorithm Derivation
EM
Lecture 14 - EM Algorithm & Factor Analysis | Stanford CS229: Machine Learning Andrew Ng -Autumn2018
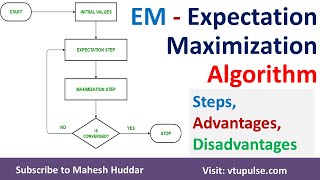
Expectation-Maximization | EM | Algorithm Steps Uses Advantages and Disadvantages by Mahesh Huddar
Expert Insights
Data is compiled from public records and verified media reports.
Last Updated: September 28, 2026
Final Thoughts
For 2026, Em Algorithm Derivation remains one of the most searched-for information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Buy my full-length statistics, data science, and SQL courses here: linktr.ee/briangreco Learn all about the I really struggled to learn this for a long time! All about the A clear visual explanation of the Expectation Maximization ( Sometimes you're just missing something, so what do we do? USEFUL LINKS Great blog post ... For more information about Stanford's Artificial Intelligence professional and graduate programs, visit: stanford.io/ai Andrew ... How do you fit Gaussian Mixture Models for clustering high-dimensional data or as generative models? The Notes: users.cs.duke.edu/~cynthia/CourseNotes/GMMEMNotes.pdf.