About to Inside Cognition S Inference Stack Rl Speculative Decoding Dflash
Looking for the latest information on Inside Cognition S Inference Stack Rl Speculative Decoding Dflash? We've compiled comprehensive data, records, and insights about Inside Cognition S Inference Stack Rl Speculative Decoding Dflash.
Important Facts
Explore the key sources for Inside Cognition S Inference Stack Rl Speculative Decoding Dflash.
Latest News
Stay updated on Inside Cognition S Inference Stack Rl Speculative Decoding Dflash's newest achievements.
S30 | DFlash: Block Diffusion for Flash Speculative Decoding
DSpark: DeepSeek's Open-Source Speed Layer That Could Change Local AI Forever
Accelerating LLM Inference: Speculative Decoding and Diffusion LLMs | AI Scale Talks EP.2
DFlash Just Made AI 6x Faster : DFlash, DeepSpec Explained
How DFlash Uses Block Diffusion to Make LLM Inference 6x Faster
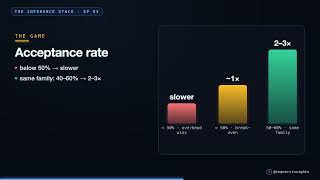
Speculative Decoding Explained: The Small Model That Makes LLMs 3x Faster (Inference Stack Ep 3)
How to Deploy AI Without Going Broke (vLLM & Inference)
Speculative Decoding: Make Your LLM Inference 2x-3x Faster
Speculative Decoding: How Draft Models 3X Local LLM Inference
Memory-Based Speculative Decoding, Explained in 3 Minutes (INLG 2026)
Data is compiled from public records and verified media reports.
Last Updated: September 26, 2026
Summary
For 2026, Inside Cognition S Inference Stack Rl Speculative Decoding Dflash remains one of the most talked-about information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
In this AI Research Roundup episode, Alex discusses the paper: ' Geometric's Pramodith Ballapuram provides a deep dive into Ready to become a certified watsonx AI Assistant Engineer? Register now and use code IBMTechYT20 for 20% off of your exam ... In today's session, Jian Chen presents An in-depth analysis covering: The The second episode of AI Scale Talks goes Large language models are incredibly powerful, but their slow, sequential token generation is a massive bottleneck. Standard ... Your GPU writes one word at a time. Master LLMs: From Transformer architecture and MoE to RLHF, DPO, and quantization (AWQ). Learn about scaling laws, ... How can a large language model generate text faster and with less energy? This animation shows LLMs are great at generating text, but speed is key in the world of computers. In this seminar, we explored
Inside Cognition S Inference Stack Rl Speculative Decoding Dflash.pdf
What is the most accurate information about Inside Cognition S Inference Stack Rl Speculative Decoding Dflash?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Inside Cognition S Inference Stack Rl Speculative Decoding Dflash.
Why is Inside Cognition S Inference Stack Rl Speculative Decoding Dflash trending right now?
Interest in Inside Cognition S Inference Stack Rl Speculative Decoding Dflash has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Inside Cognition S Inference Stack Rl Speculative Decoding Dflash?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Inside Cognition S Inference Stack Rl Speculative Decoding Dflash updated?
We regularly update our database with the latest information, media, and analysis related to Inside Cognition S Inference Stack Rl Speculative Decoding Dflash.