Overview of Transformers Low Level Api 4 Bit Quantization Memory Optimization Llm Code Infinity
Looking for the latest information on Transformers Low Level Api 4 Bit Quantization Memory Optimization Llm Code Infinity? We've researched comprehensive data, records, and insights about Transformers Low Level Api 4 Bit Quantization Memory Optimization Llm Code Infinity.
Key Details
Explore the key sources for Transformers Low Level Api 4 Bit Quantization Memory Optimization Llm Code Infinity.
Latest News
Stay updated on Transformers Low Level Api 4 Bit Quantization Memory Optimization Llm Code Infinity's newest achievements.
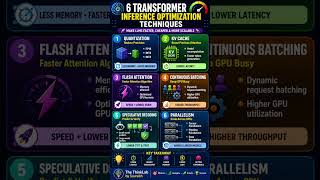
🚀 6 Transformer Inference Optimization Techniques Every AI Engineer Should Know
8-Bit Quantisation Demistyfied With Transformers : A Solution For Reducing LLM Sizes
LLM Quantization: Shrink Your Model, Save Tokens
Why Does Your Local Model Crash at 32k Tokens
Breaking the 1.58-bit Barrier for Ternary LLMs
You can shrink giant LLMs to 3–4 bits with almost no loss
What is Prompt Caching Optimize LLM Latency with AI Transformers
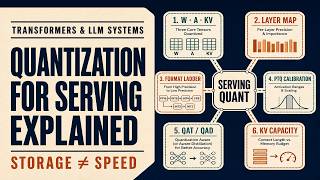
LLM Quantization for Serving (Weights, Activations, and KV Cache Quantization Explained)
how to quantize an llm with gguf or awq
Full Guide
Data is compiled from public records and verified media reports.
Last Updated: September 27, 2026
Future Outlook
For 2026, Transformers Low Level Api 4 Bit Quantization Memory Optimization Llm Code Infinity remains one of the most searched-for information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Learn how to efficiently run large language models Llama 3.1, Phi-3, and Gemma 2 on consumer hardware using Hugging ... You've probably heard about 8-bit or Quantisation is rounding off the parameters to smaller sized datatype, and still maintain the accuracy. The video explains the ... Stop fighting VRAM limits! Learn how How the new breakthrough in ternary Ready to become a certified watsonx Generative AI Engineer? Register now and use Free newsletter: multiagentacademy.substack.com/
Transformers Low Level Api 4 Bit Quantization Memory Optimization Llm Code Infinity.pdf
What is the most accurate information about Transformers Low Level Api 4 Bit Quantization Memory Optimization Llm Code Infinity?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Transformers Low Level Api 4 Bit Quantization Memory Optimization Llm Code Infinity.
Why is Transformers Low Level Api 4 Bit Quantization Memory Optimization Llm Code Infinity trending right now?
Interest in Transformers Low Level Api 4 Bit Quantization Memory Optimization Llm Code Infinity has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Transformers Low Level Api 4 Bit Quantization Memory Optimization Llm Code Infinity?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Transformers Low Level Api 4 Bit Quantization Memory Optimization Llm Code Infinity updated?
We regularly update our database with the latest information, media, and analysis related to Transformers Low Level Api 4 Bit Quantization Memory Optimization Llm Code Infinity.